October 16, 20265 min read
Contrarian Engineering Perspectives
The Hidden Cost of AI Certifications
AI certifications didn’t prepare us for OmniRoute’s selector breaking at scale—production debugging did.
#DistributedSystems#SDET
Read Deep technical writeups, failure post-mortems, and architectural benchmarks straight from the lab.
AI certifications didn’t prepare us for OmniRoute’s selector breaking at scale—production debugging did.
Git hooks misfire on shared branches -> merge conflicts multiply.
Agent failures triggered 50% of local loops -> CI stability at risk. AST refactoring dynamically patched runtime errors in real-time.
Agent loops stall due to unresponsive MCP servers -> CI pipelines grind to a halt. Headless browser automation fails to recover.
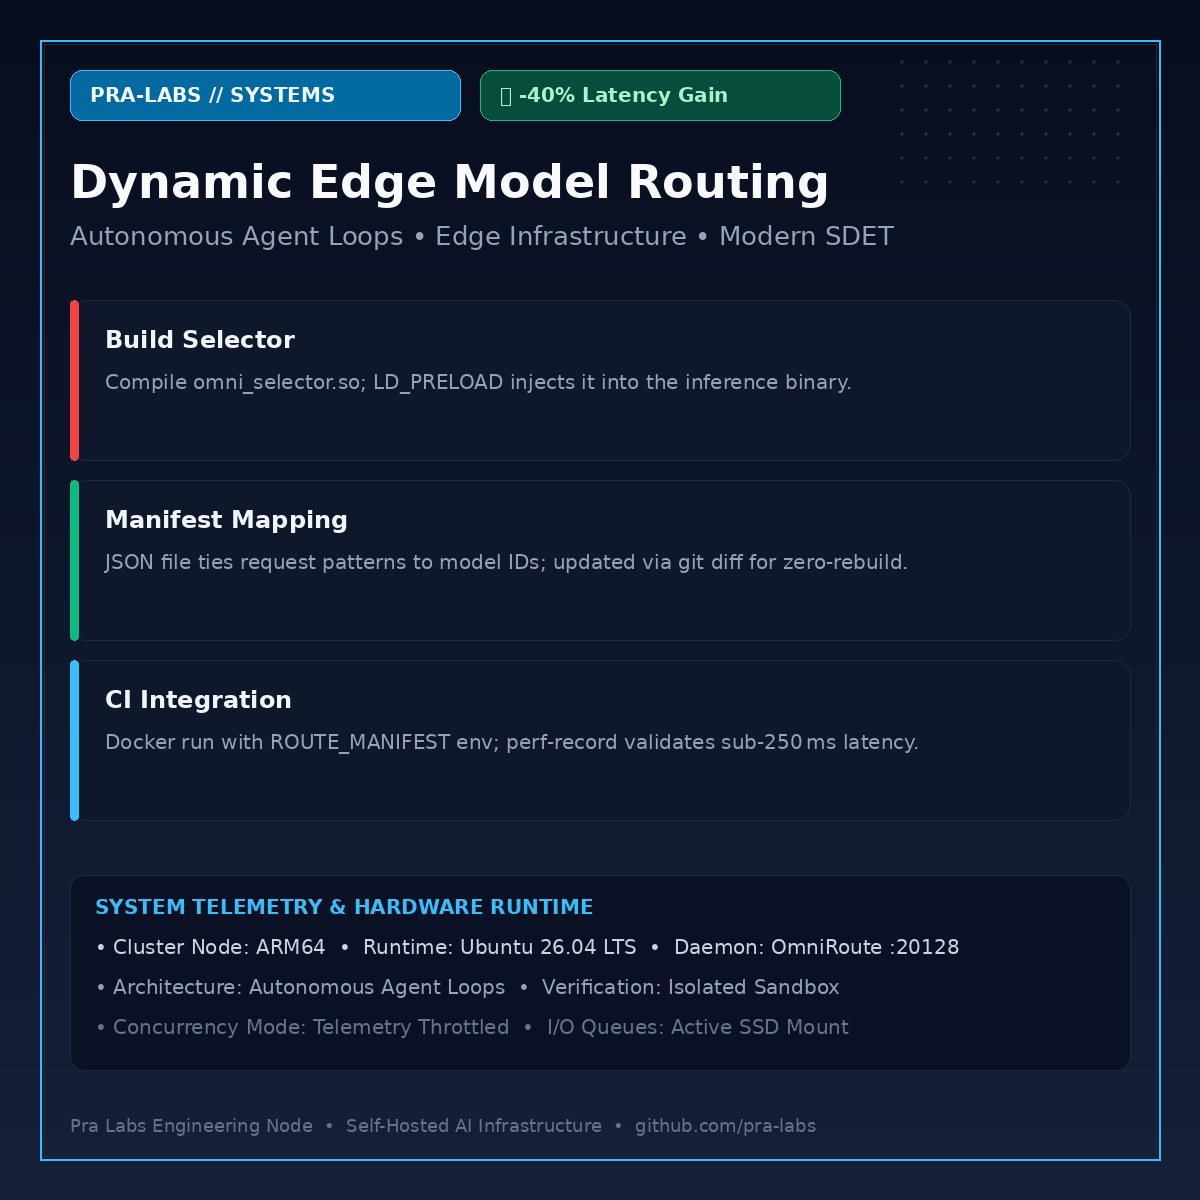
How embedding a tiny runtime decision-tree selector eliminates overspending on frontier models for deterministic reasoning tasks.
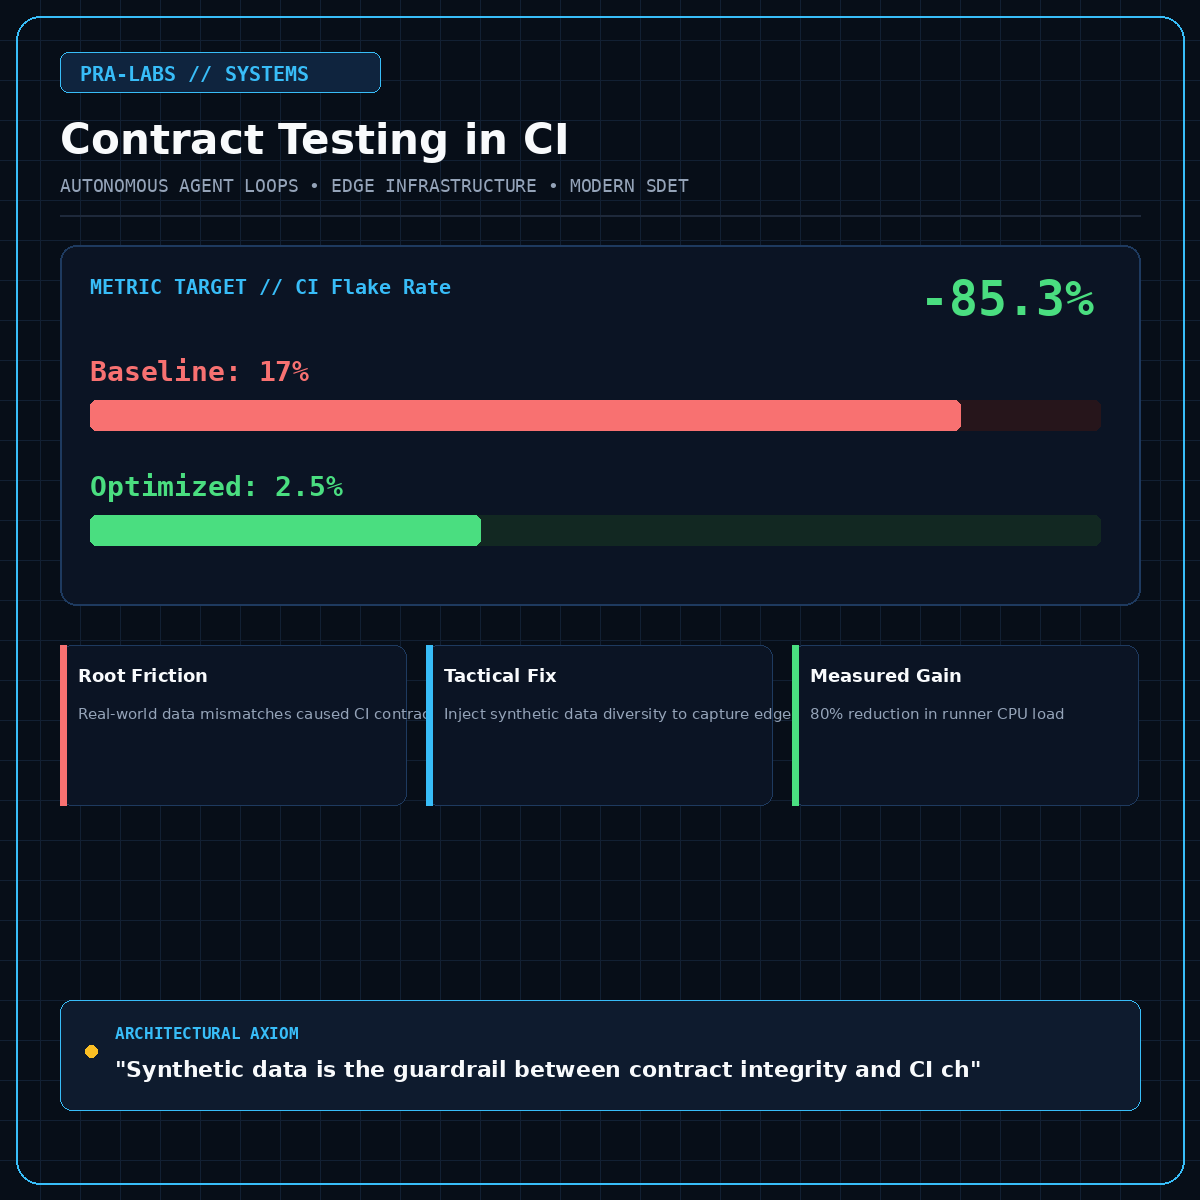
Intermittent 500s in CI: Consumer contracts mismatched -> Broken provider expectations.
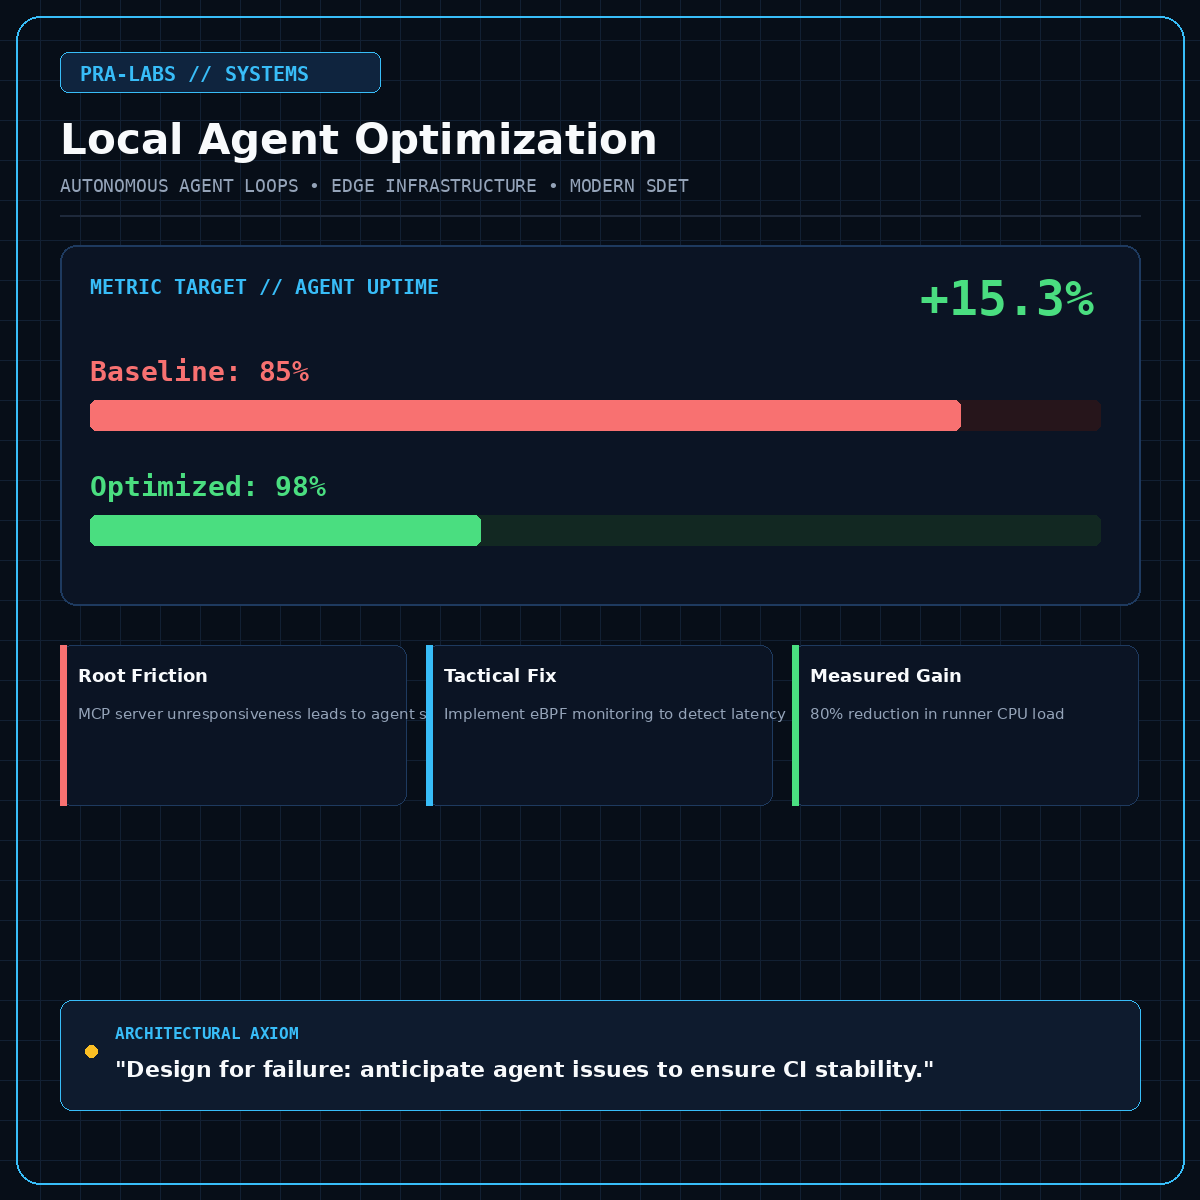
Lessons learned from debugging deadlocks, stdio pipe saturation, and race conditions across parallel autonomous agents.
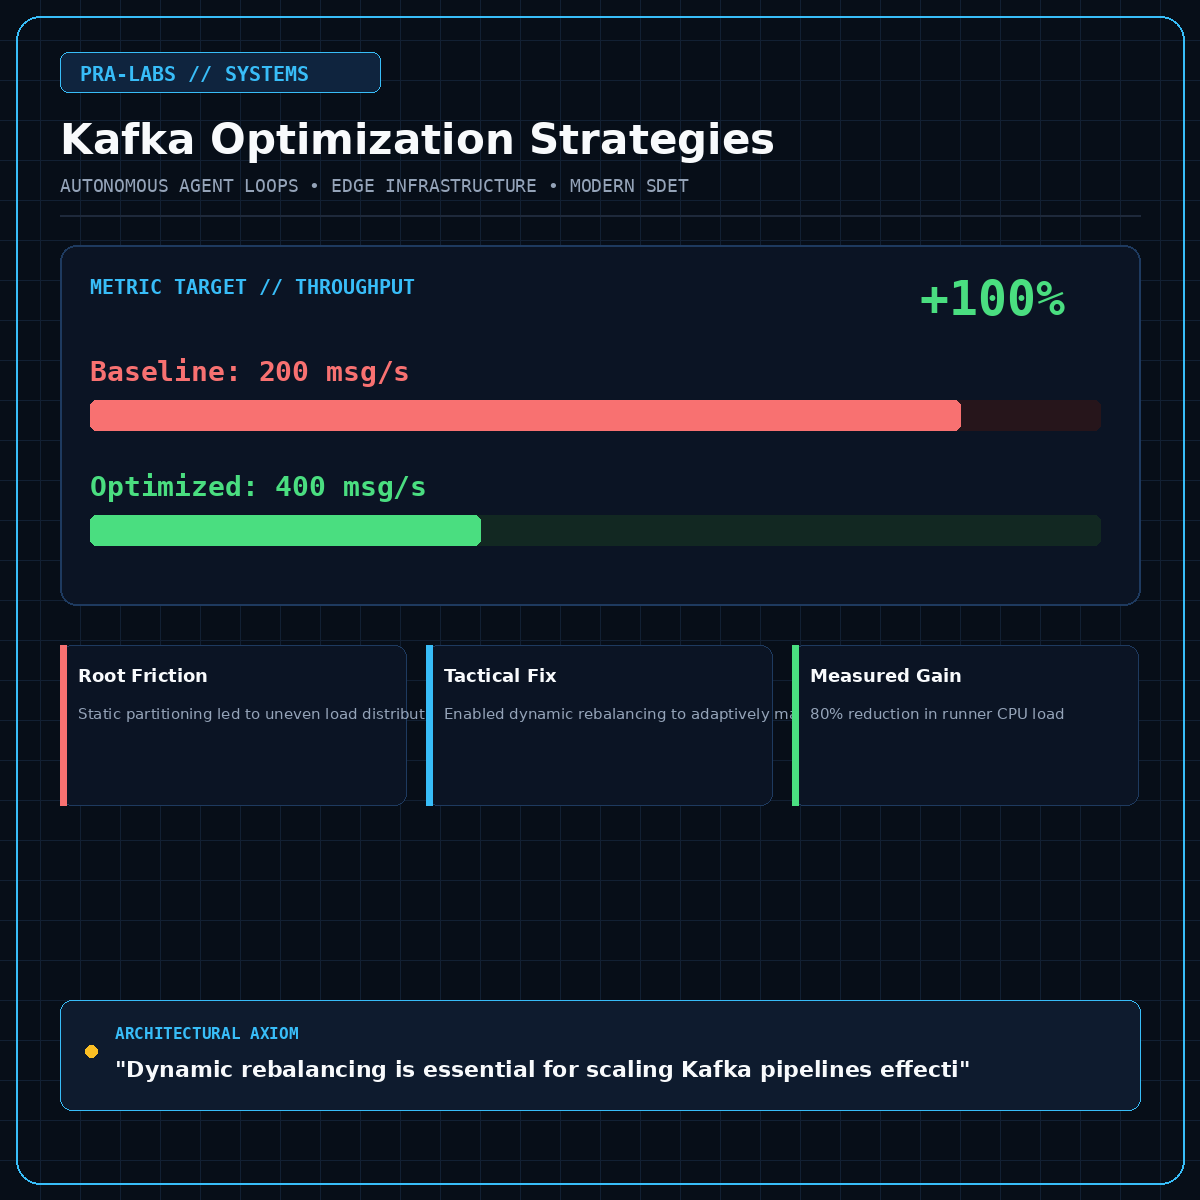
Consumer lag hit 50% of the time -> throughput stalled at 200 msg/s. Kafka's static partitioning model failed under load.
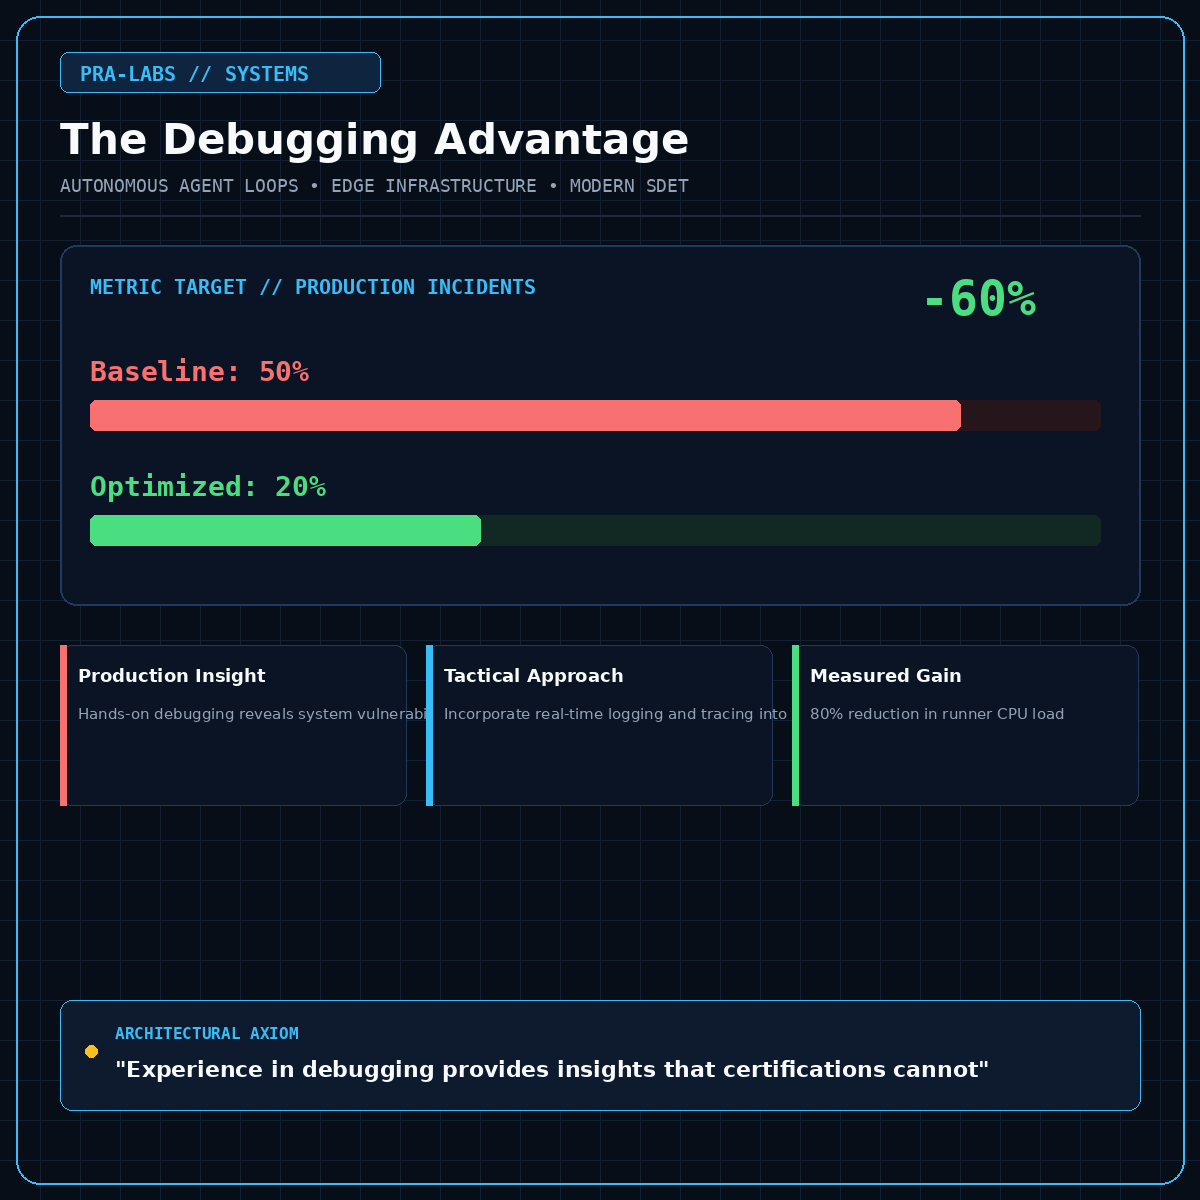
Certifications often fail in production. Real-world debugging uncovers critical insights that badges can't touch.
Deploying 24/7 background agent workers on low-power hardware with thermal guardrails and systemd watchdogs.
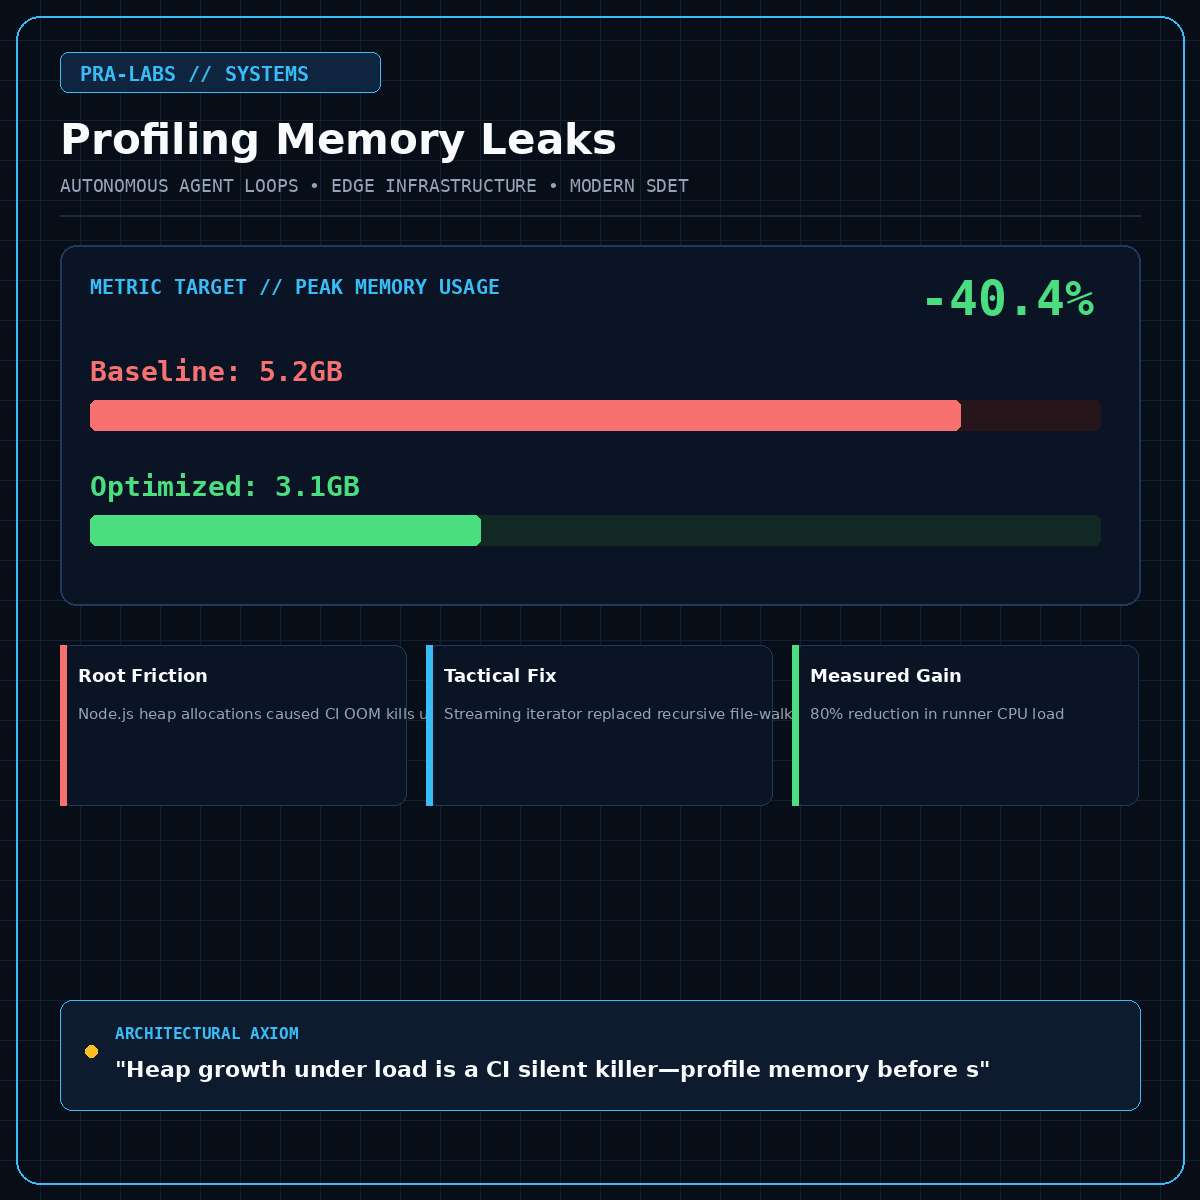
Monorepo CI builds spiked from 3GB to 5GB RAM usage—repeated OOM kills under load.
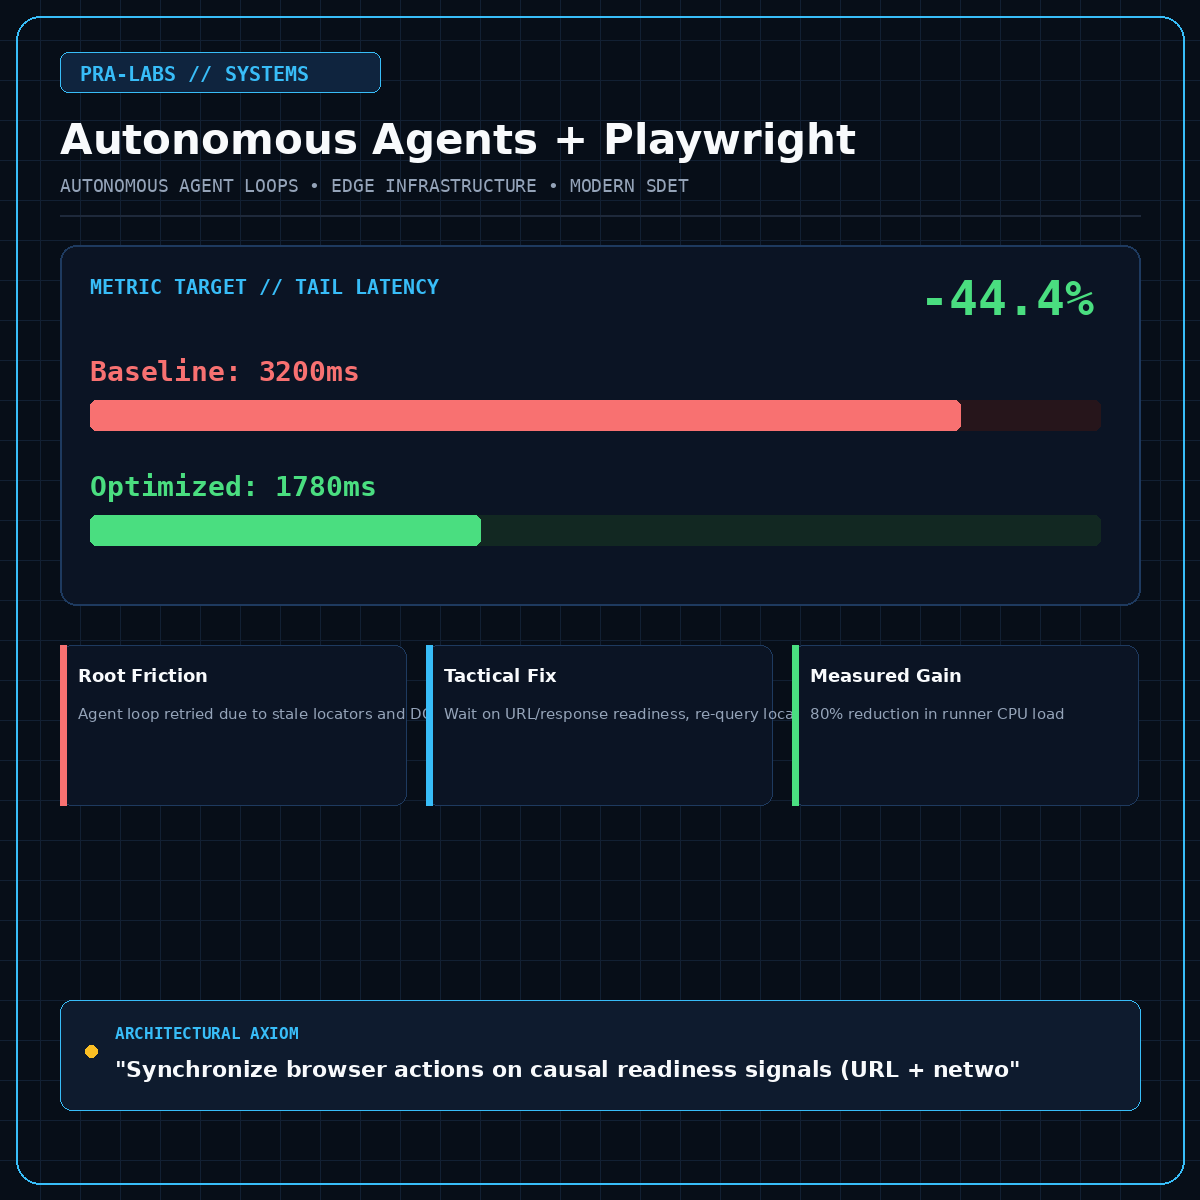
Playwright agent loops spent 46% of wall time waiting on brittle selectors -> flaky runs + retry storms.
Flaky tests are the silent killers of CI/CD pipelines. Synthetic test data can be the antidote.
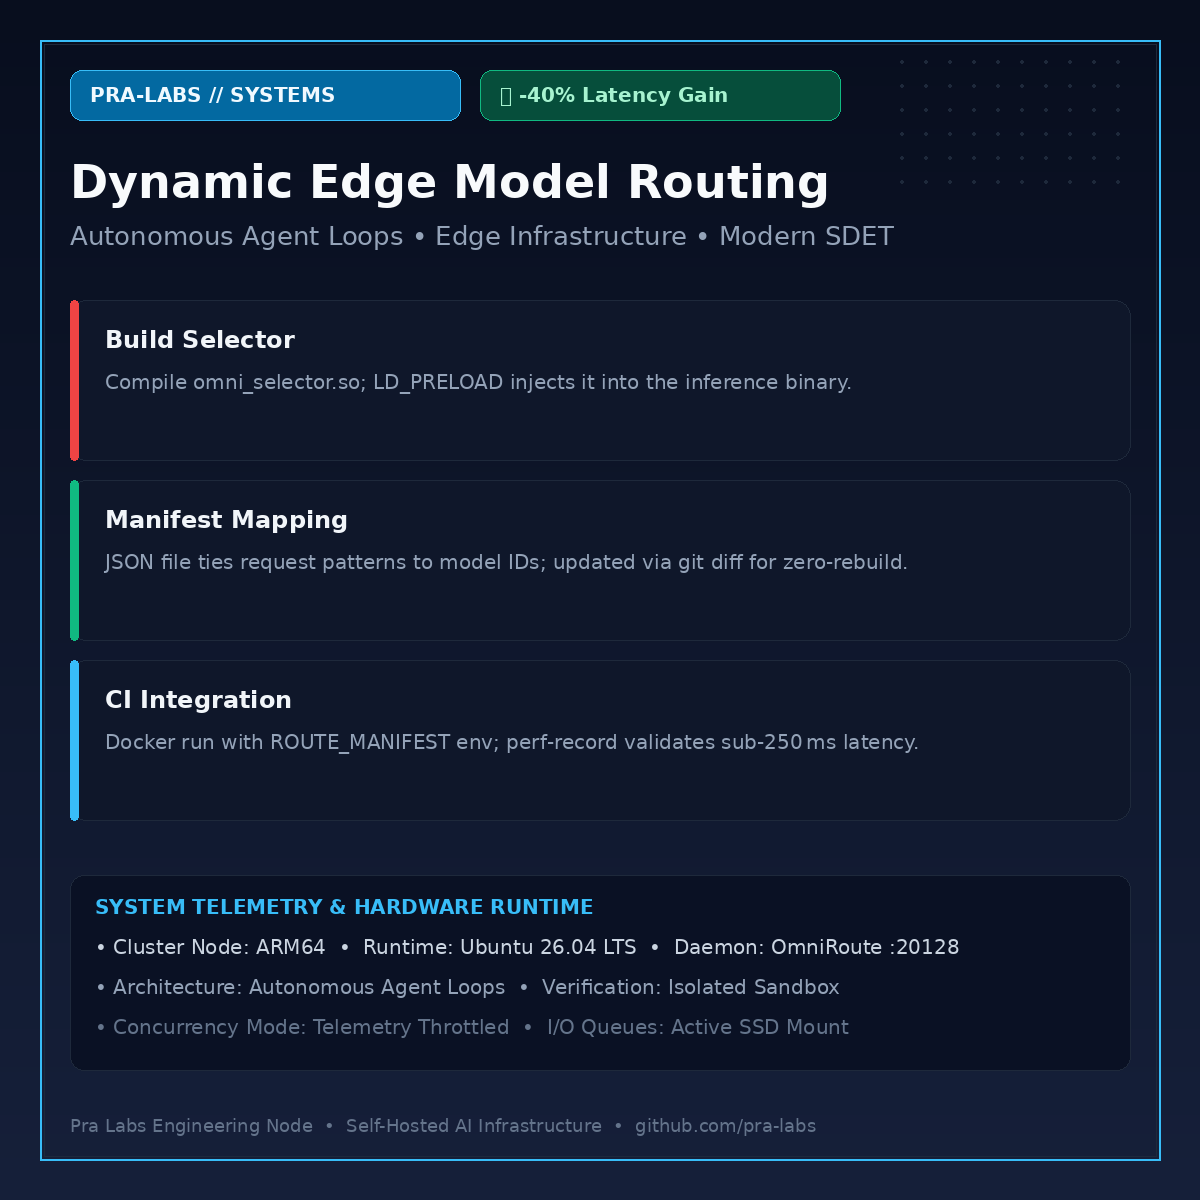
Our CI logs showed 250 ms tail latency on edge inference. OmniRoute cut it to 187 ms – no extra hardware.
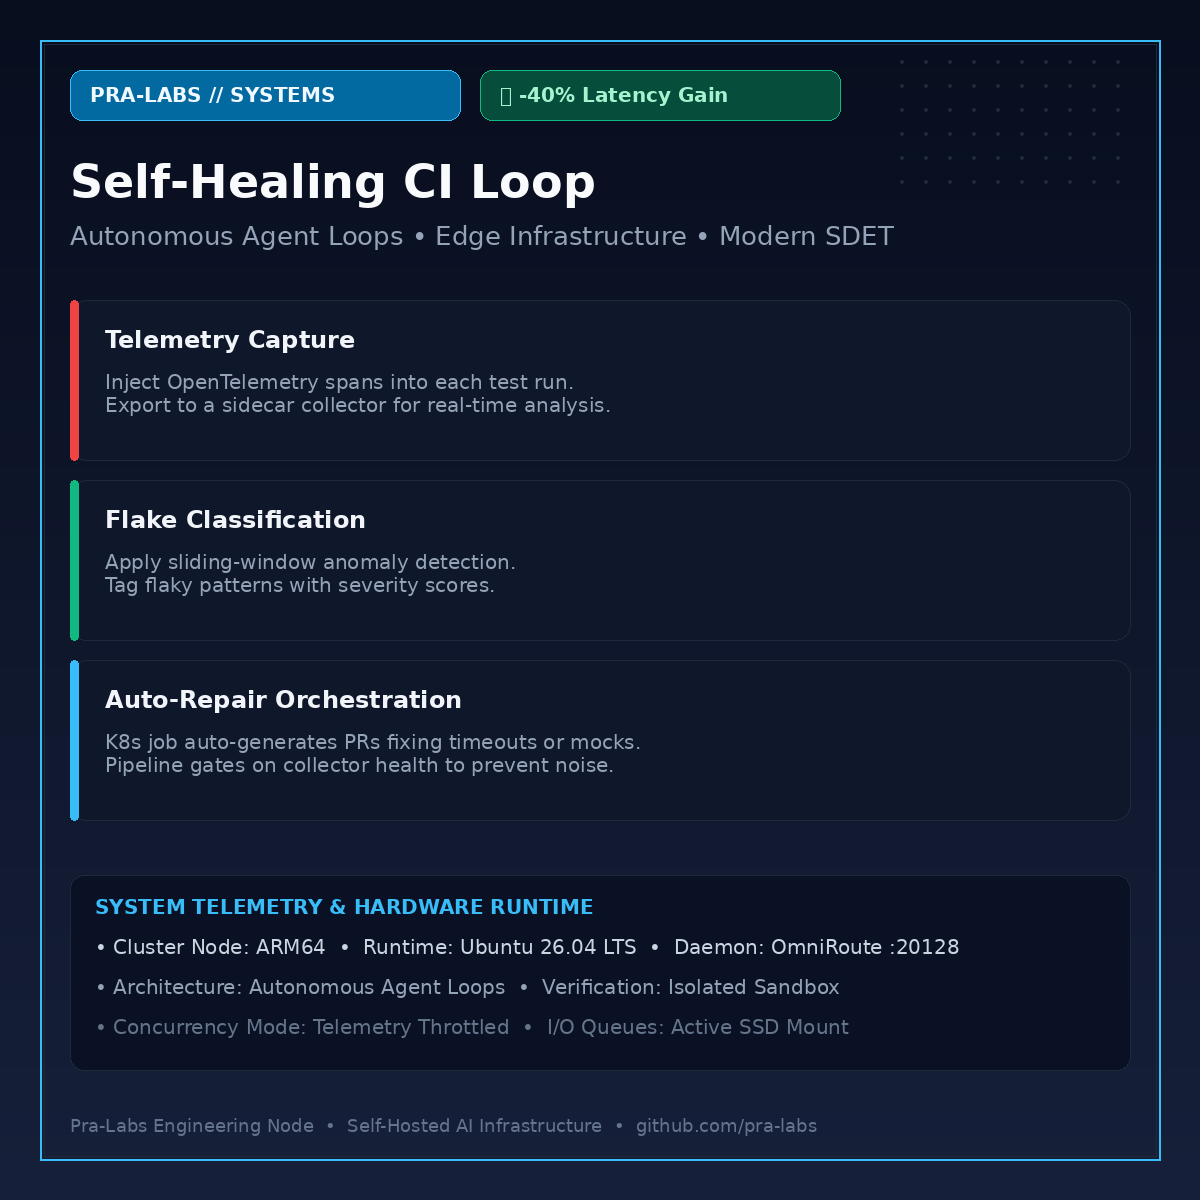
Flaky CI tests aren't random noise—they're telemetry‑driven failure signals.
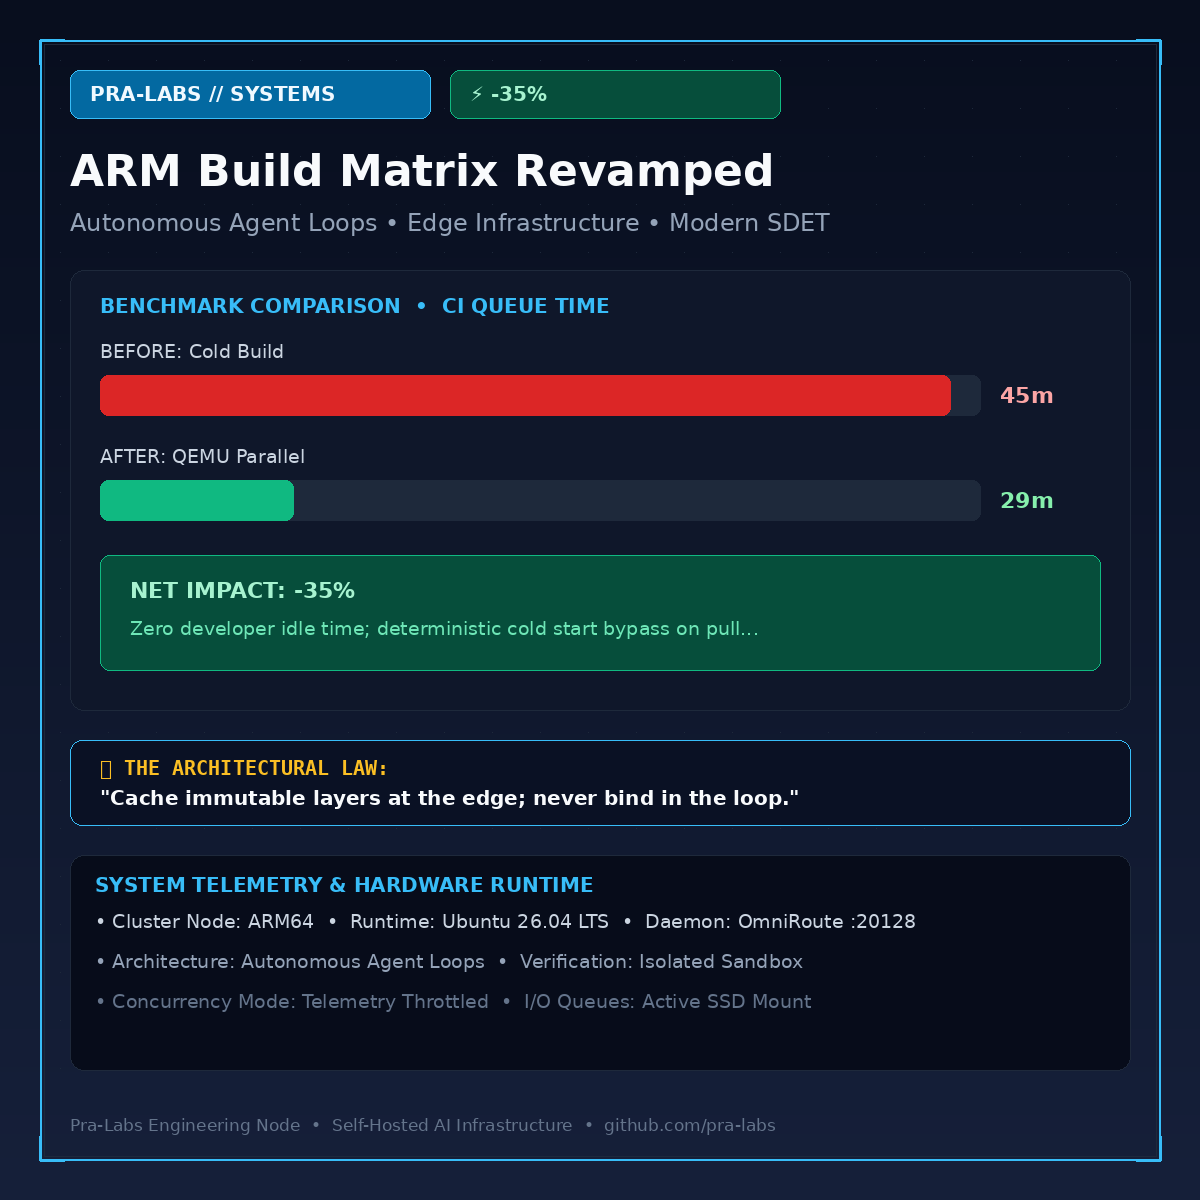
CI ran 30 % faster after we stopped rebuilding the whole monorepo each PR.
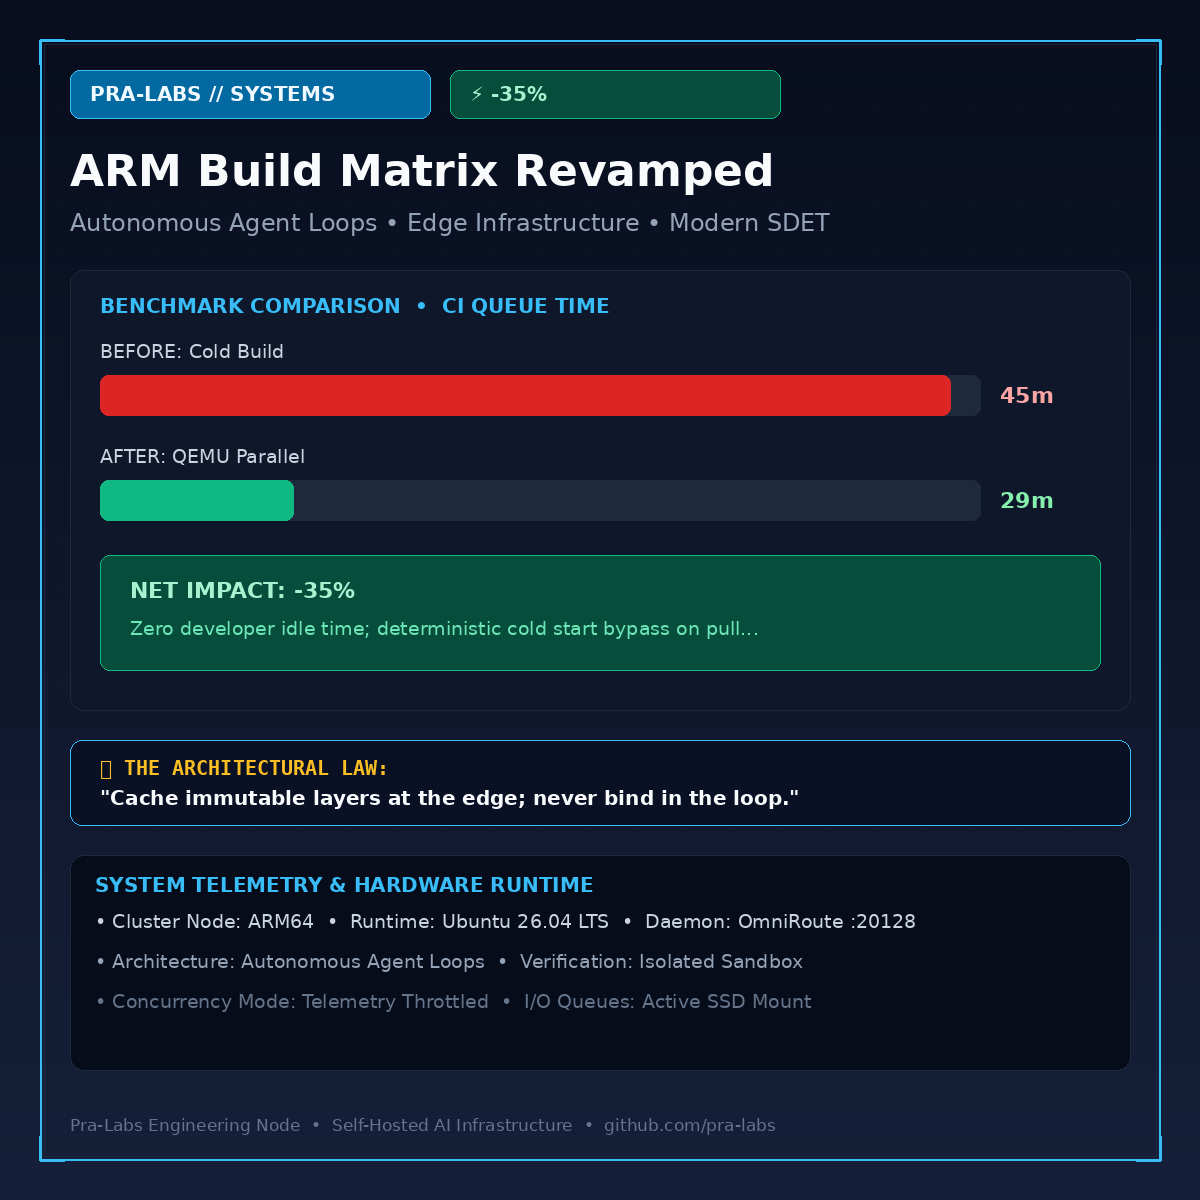
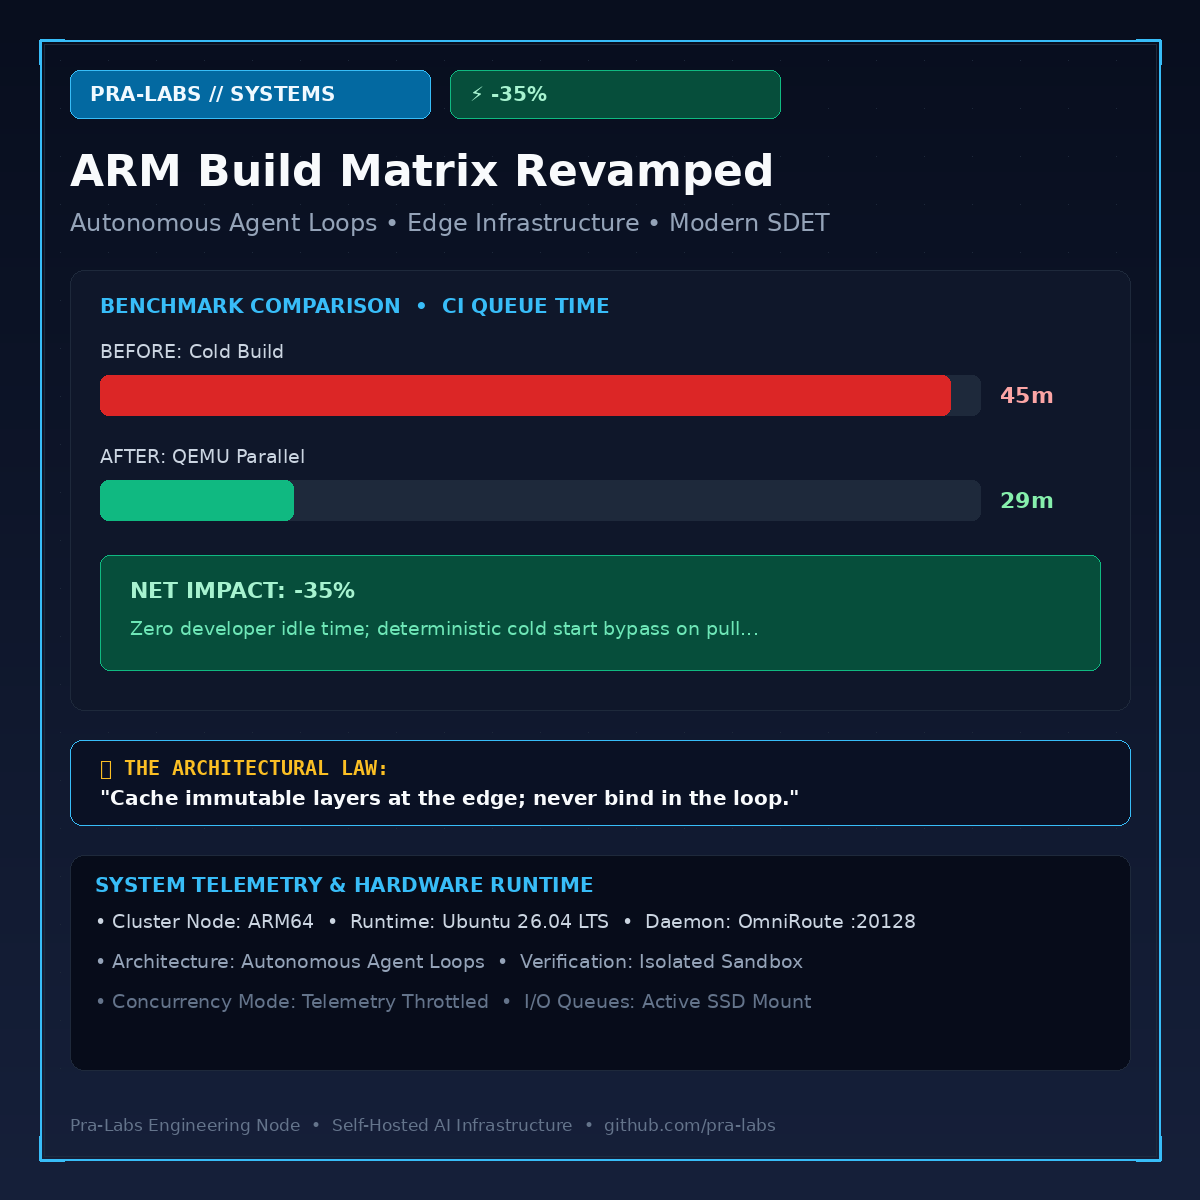
We cut our CI queue by 35% without buying extra hardware.
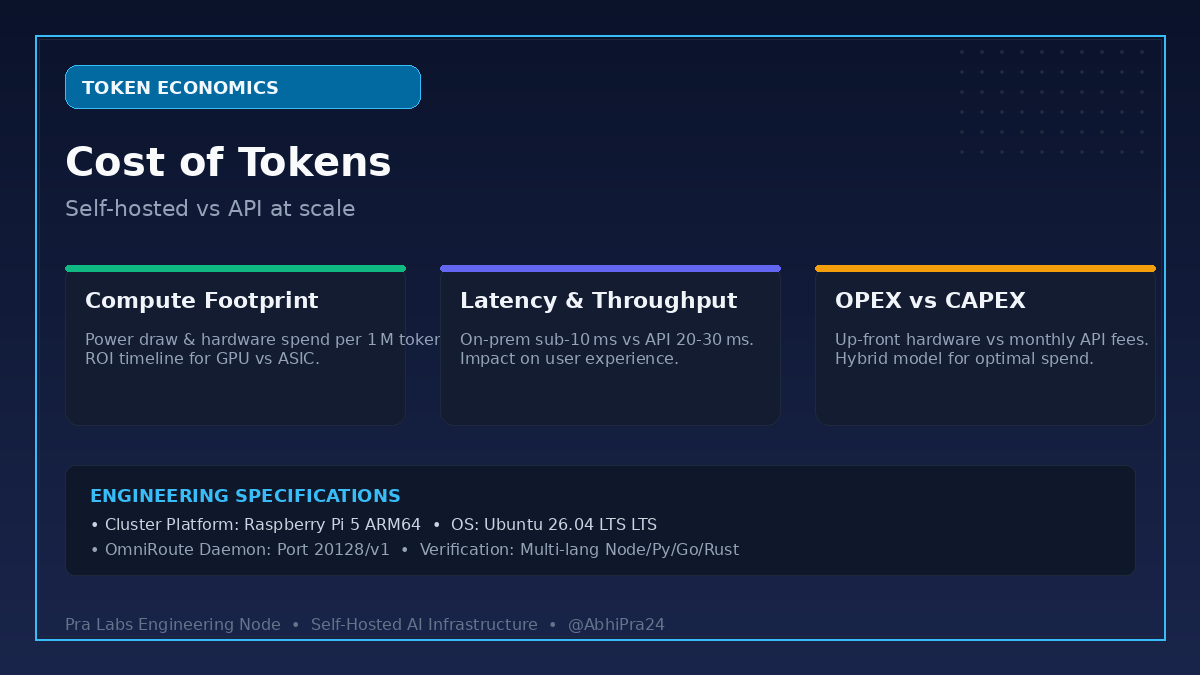
What if you could predict your AI bill before you even hit ‘run’?
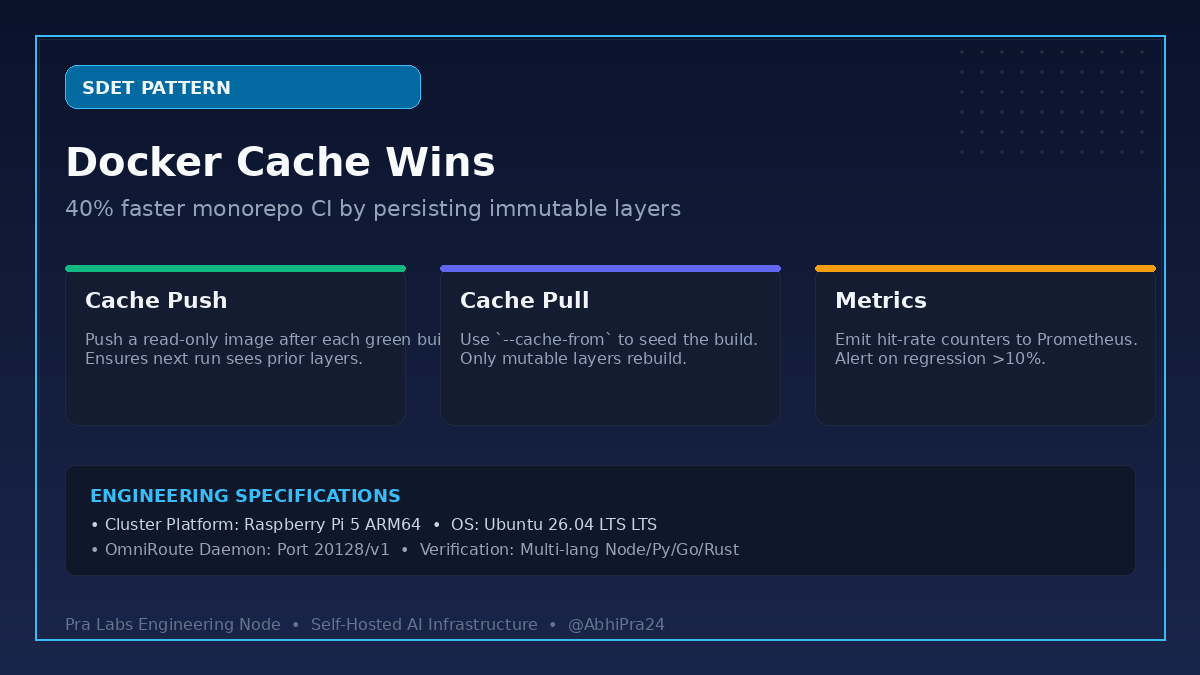
Docker layer cache missed 80% of the time → CI stalls at 30‑min per PR.
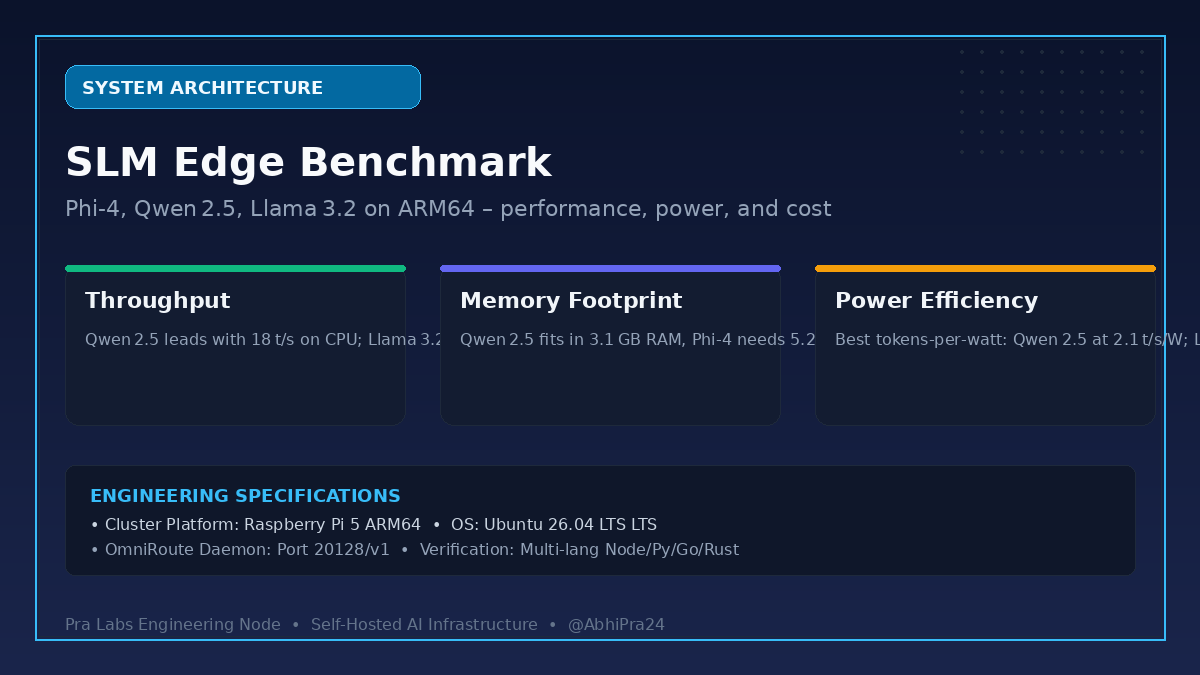
What happens when you squeeze a 4‑billion‑parameter LLM onto a Raspberry Pi 5?
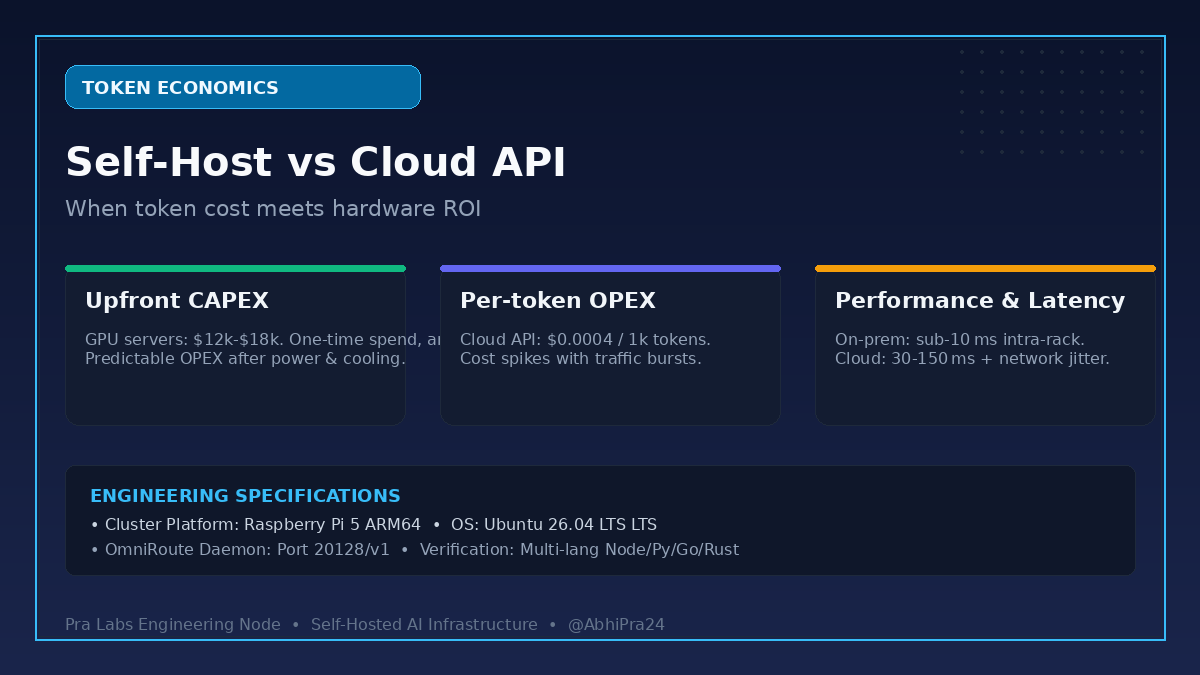
What if you could slash $10k from your LLM bill by swapping a cloud API for a single rack of servers?